Tag: llamacpp
-
Are model/hardware specific inference engines the future of local LLMs?
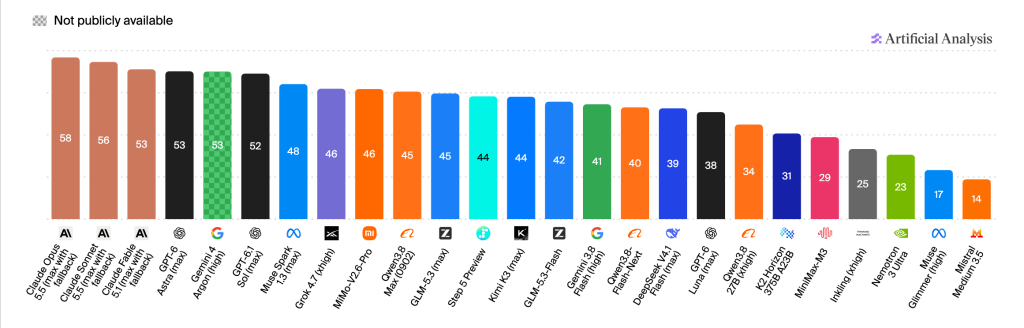
Three weeks of running Qwen3.8-27B and Flash-Next on two, then three, RTX 3060s: exact flags, measured prefill and decode speeds, and the question of whether general-purpose inference engines are the future.
