Tag: llm
-
Are model/hardware specific inference engines the future of local LLMs?
Three weeks of running Qwen3.8-27B and Flash-Next on two, then three, RTX 3060s: exact flags, measured prefill and decode speeds, and the question of whether general-purpose inference engines are the future.
-
I gave my coding agent a browser
Coding agents are remarkably capable right up until they need information that isn’t already sitting inside their context window. Then things get interesting. I use coding agents heavily, particularly Pi, and one recurring annoyance was giving the agent access to the web without dragging an entire browser-shaped dependency tree into the workflow. Sometimes the agent…
-
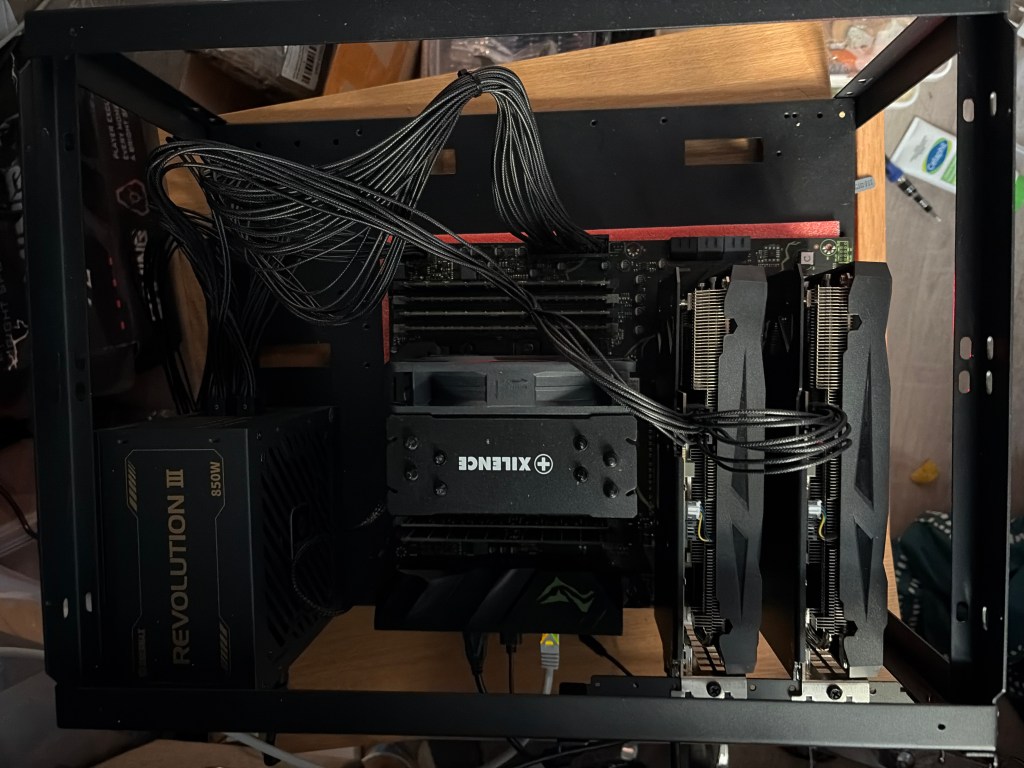
Building my first AI rig (ft. AliExpress)
My work is full time coding. My colleagues: Claude Code, Opencode, Pi. Recently our collaboration has increased multi-fold. So I decided to do the reasonable thing: ask them to move in with me. I am deeply fascinated by AI. If you think about it, it’s just raw matrix math running at an unthinkable scale to…
