My work is full time coding. My colleagues: Claude Code, Opencode, Pi. Recently our collaboration has increased multi-fold. so I decided to do the reasonable thing: ask them to move in with me.
I am deeply fascinated by AI. If you think about it, it’s just raw matrix math running at an unthinkable scale to simulate though. This fact alone gives me a huge kick. My recent obsession has been trying out different models and harnesses the second they drop, and trying to increase efficiency of these harnesses through plugins, extensions, and proxies.
This was my everyday life, till Qwen3.8-27B came out.
I tried it on RunPod and was blown away. First time a local model, which in my opinion and usage was clearly on par or even better sometimes than cloud models. This was a catalyst that pushed me to set up my own rig.
I YOLOed the entire build and sourced almost everything from AliExpress (except RAM – from eBay). It’s a pile of Xeon-era server hardware, Chinese X99 engineering, ECC memory, and consumer GPUs.
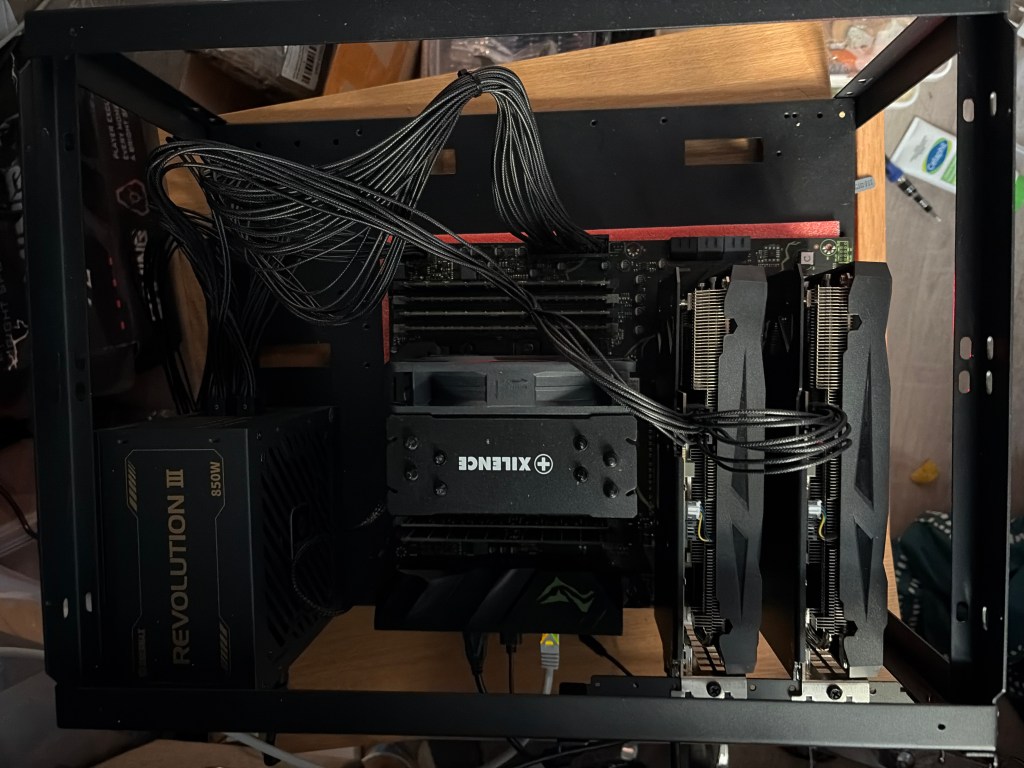
Spec. – 14 CPU cores · 28 threads · 96 GB 4 channel DDR4 ECC RAM · 2× RTX 3060 · 24 GB aggregate VRAM · 256 GB NVMe
CPU
Intel Xeon E5-2690 v4
14 cores / 28 threads
2.6 GHz base clock, up to 3.5 GHz boost
Broadwell-EP architecture
Motherboard
MACHINIST X99-MR9S V6.2
Intel X99 / LGA2011-3 platform
AMI BIOS 5.11
I got the CPU and the Motherboard together as a bundle offer from AliExpress for 130€ (I was feeling lucky).
GPU – AliExpress (300€ for one when I bought it. Now its 430€. Again feeling lucky.)
2 × NVIDIA SOYO RTX 3060
12 GB GDDR6 VRAM per GPU
24 GB aggregate VRAM
Memory
96 GB DDR4-2133 ECC Registered memory
4 × 16 GB RDIMM – eBay (150€ for four)
4 × 8 GB RDIMM – AliExpress (150€ for four. Not feeling lucky)
8 DIMMs total
Storage – AliExpress 40€
256 GB Taimi NVMe SSD
M.2 2280
PCIe Gen3 ×4
Software
Operating System: Debian GNU/Linux 13 (Trixie)
Architecture: x86-64
Kernel: Linux 6.12
Total Cost – About 1200€ including the server rack and misc.
Now, coming to the performance, I tested it with the ukisai/Swift-Qwen3.8-27B-GGUF IQ4_XS* (huggingface) using BeeLlama (a llamacpp fork)
The results were – Prompt processing: 650–700 tokens per second · Decode speed: 40–45 tokens per second (with MTP) · Context: 190K KVarn4/KVarn2 KV
I’ve been using it as my daily driver for more than a week. So far, I haven’t noticed any degradation in output quality as the context grows. For a machine assembled from bargain-bin server parts and questionable marketplace listings, I’m pretty happy with it.
Next up: why BeeLlama, how the server is configured, and which knobs I turned until the numbers looked encouraging. Stay tuned, I guess.
*ukisai/Swift-Qwen3.8-27B-GGUF IQ4_XS is a finetuned Qwen3.8-27B. It reduces the overthinking problem of the original Qwen model.
 tokenBuffalo

Leave a comment